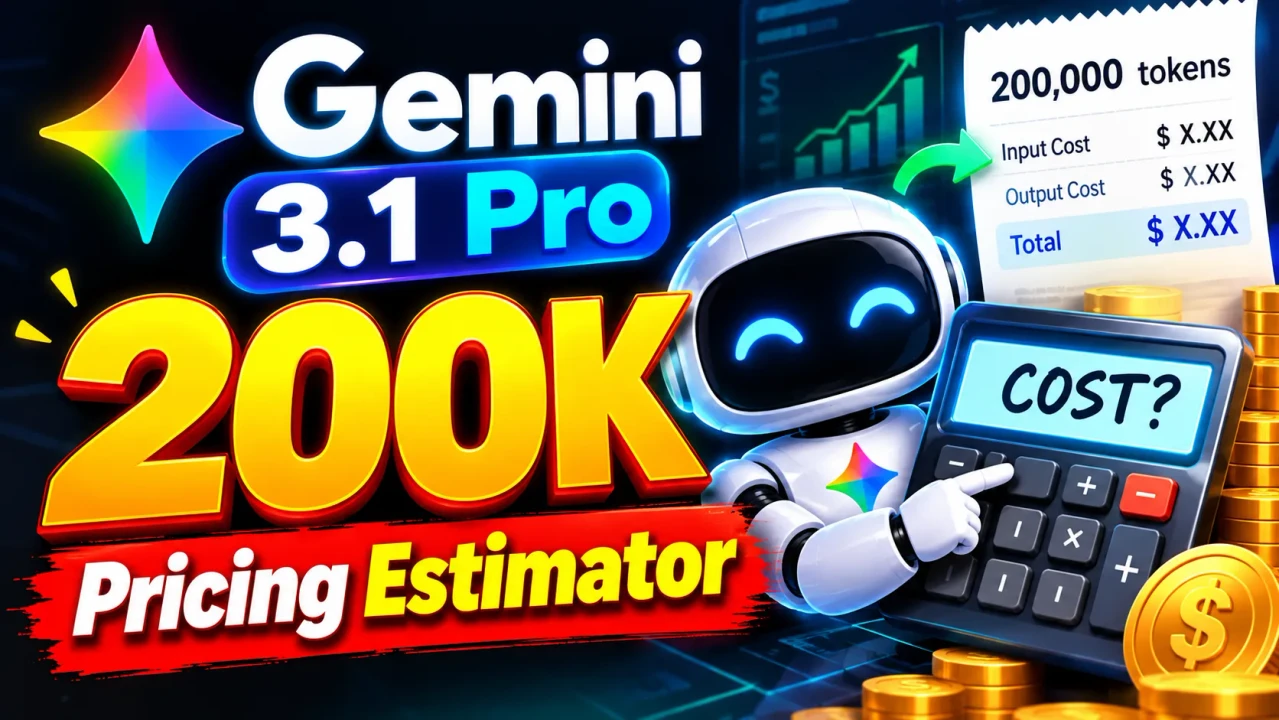
Gemini 3.1 Pro 200k Pricing Estimator
Quick answer: The Gemini 3.1 Pro 200k Pricing Estimator is intended to help users estimate the cost of processing AI workloads with Gemini 3.1 Pro when the applicable input context is up to 200,000 tokens. To calculate a reliable estimate, the model's actual pricing tiers, input and output token counts, and any applicable discounts must be confirmed.
This estimator is designed for developers, AI application builders, product teams, and businesses evaluating the potential cost of using Gemini models. It focuses on token-based API expenses rather than a general-purpose subscription or cloud-budget calculation.
What Does the Estimator Calculate?
AI inference costs generally depend on the number of input tokens sent to the model and the number of output tokens generated. Some pricing schedules also distinguish between standard prompts, cached input, batch processing, or different context-length tiers. These rates must be verified against the pricing schedule applicable to the exact model and API.
- Input tokens: Tokens used by the prompt, conversation history, and other supported input content.
- Output tokens: Tokens generated by the model in its response.
- Context length: The total context supported by the selected model configuration. A 200,000-token workload should not be assumed to have the same rate as a shorter prompt unless the official pricing rules confirm it.
- Estimated cost: A calculated monetary estimate based on token usage and verified rates.
The name of the tool identifies the intended model and context-size scenario, but the actual pricing configuration and calculator implementation have not been provided. Therefore, the calculations and interface options below should be treated as implementation guidance, not as confirmation of the live tool's existing behavior.
How to Use Gemini 3.1 Pro 200k Pricing Estimator?
- Confirm the model: Select the exact Gemini model identifier and API pricing schedule. Do not substitute another model's rates.
- Enter input usage: Supply the expected input token count for an individual request or a group of requests.
- Enter output usage: Supply the expected generated-token count.
- Apply pricing conditions: Include caching, batch-processing rates, or context-based pricing tiers only if supported by the estimator and the applicable official pricing schedule.
- Review the estimate: Check the input cost, output cost, total estimated cost, and currency before using the result for budgeting.
Input and Output Example
The following is a hypothetical example illustrating token-based cost arithmetic. It does not represent verified Gemini 3.1 Pro prices.
Example inputs:
Input tokens: 150,000
Output tokens: 10,000
Assumed input rate: $1.00 per 1 million tokens
Assumed output rate: $5.00 per 1 million tokens

Input cost:
150,000 / 1,000,000 × $1.00 = $0.15

Output cost:
10,000 / 1,000,000 × $5.00 = $0.05

Illustrative total:
$0.15 + $0.05 = $0.20
The example demonstrates the calculation method only. The assumed rates are placeholders for arithmetic and must not be published or presented as actual Google pricing.
Token Pricing Reference
| Pricing component | Calculation | What to verify |
|---|---|---|
| Input tokens | Input tokens ÷ 1,000,000 × input rate | Official rate for the exact model and context tier |
| Output tokens | Output tokens ÷ 1,000,000 × output rate | Official generated-token rate |
| Cached input | Cached tokens ÷ 1,000,000 × cached-input rate | Whether caching is supported and separately priced |
| Batch processing | Eligible batch usage × applicable batch rate | Batch eligibility, rate, and processing conditions |
| Total estimate | Input cost + output cost + other applicable charges | Currency, rounding, and any excluded charges |
How the Pricing Calculation Works
For a basic token-priced request, the estimate can be expressed as:
Input cost = (Input tokens / 1,000,000) × Input rate
Output cost = (Output tokens / 1,000,000) × Output rate
Estimated total = Input cost + Output cost
Here, input and output rates are expressed in the same currency per million tokens. If the official pricing schedule includes multiple tiers or additional billable components, the calculation must be adjusted to reflect those rules.
For repeated requests, the basic estimate becomes:
Total estimated cost =
Number of requests ×
(Input cost per request + Output cost per request)
This repeated-request formula assumes that each request has the same token usage and pricing conditions. For variable workloads, calculate each usage category separately and sum the results.
200,000-Token Context: Important Distinctions
A context-window limit and a billing threshold are not necessarily the same thing. A model may support a given context size without every request using that many tokens. Likewise, an input consisting of 200,000 tokens is different from 200,000 input tokens repeated across hundreds of requests.
- Context capacity: The maximum context the selected model can process under its documented conditions.
- Actual usage: The tokens billed for a particular request according to the applicable pricing rules.
- Repeated usage: The combined token volume across all requests in a workload.
- Output generation: Generated tokens are typically calculated separately from input tokens when the official schedule specifies distinct rates.
Edge Cases and Limitations
- Zero tokens: A zero-token component contributes zero to the basic token-cost formula, but other applicable charges may remain.
- Context over the limit: Requests that exceed the model's supported context must not be treated as valid estimates without checking the model's documented limits.
- Mixed pricing tiers: If different portions of a request are priced differently, calculate each portion using its corresponding rate.
- Cached tokens: Do not subtract cached tokens from ordinary input usage or apply a caching discount unless the pricing rules explicitly define that treatment.
- Variable response sizes: Use representative or measured output-token counts rather than assuming every response has the same length.
- Currency and rounding: Keep the rate and result in the same currency, and retain sufficient decimal precision for small estimates.
- Unavailable rates: If the exact model's official rates cannot be confirmed, label the result as illustrative rather than a verified price estimate.
Official Pricing and Model Documentation
Before publishing or relying on a live estimate, verify the model identifier, context limits, and current billing rules in Google's primary documentation:
These references should be used to validate pricing rather than assuming that the word “200k” identifies a separate billing tier. Model availability, rate schedules, and API terms can change over time.
Technical Disclaimer: Token-based calculations are estimates, not invoices. Actual charges depend on the model and service used, billable token counts, applicable pricing conditions, and the provider's current billing rules.
Author: Daniel Brooks — AI Systems and Cloud Cost Analyst.
Technical Review: The estimator's documented methodology should be checked against Google's official model and pricing documentation before its rates are represented as current or authoritative.