Gemini Api Caching Cost Estimator For Token Savings
Estimate Gemini API costs with cached tokens, request volume, and cache TTL. Compare cached and uncached usage to understand potential savings before deployment.
Please complete this field to continue.
Please complete this field to continue.
Please complete this field to continue.
Please complete this field to continue.
Please complete this field to continue.
Please complete this field to continue.
Results
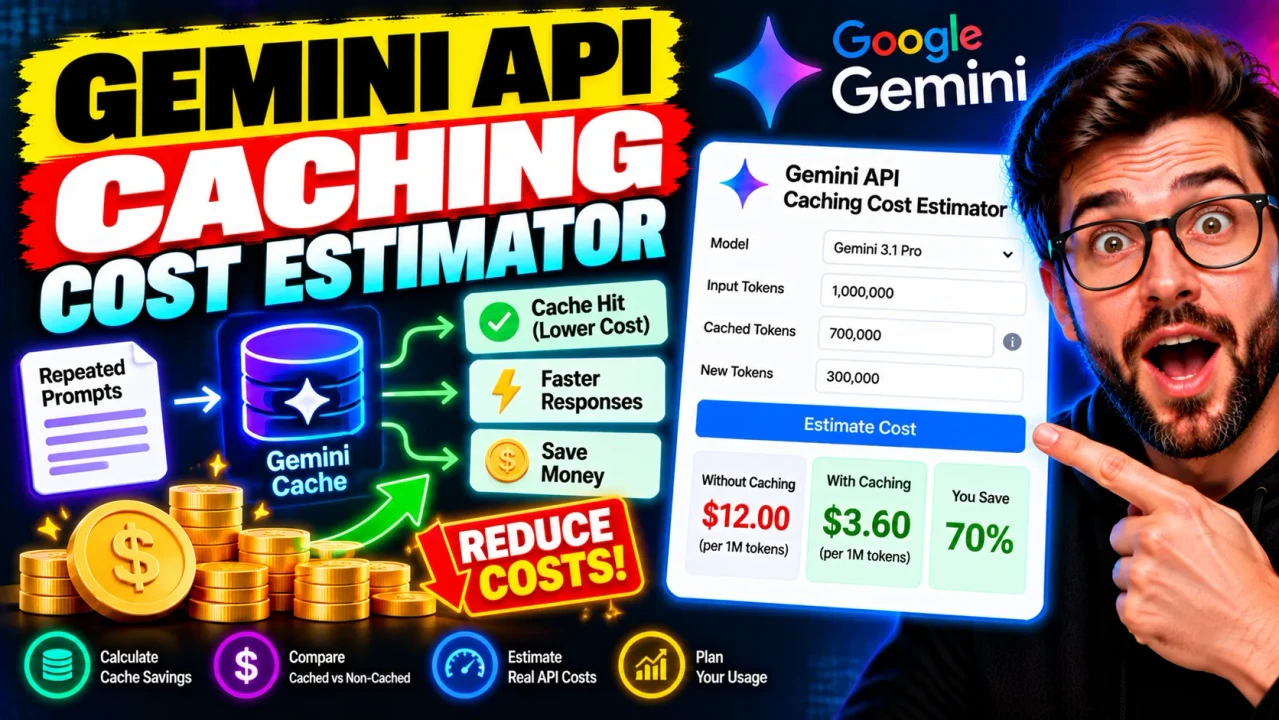
Gemini API Caching Cost Estimator
Quick answer: The Gemini API Caching Cost Estimator is a cost-calculation utility for evaluating how context caching can affect Google Gemini API expenses. It helps estimate cached input costs, cache storage charges, uncached input costs, and potential savings using token volumes, request frequency, cache duration, and applicable model pricing.
Context caching can reduce repeated input-token costs when multiple Gemini API requests reuse the same large context, such as system instructions, documentation, source code, or reference material. However, caching also introduces storage costs and does not eliminate charges for new input tokens or generated output. Estimating both sides helps determine whether caching is financially beneficial for a particular workload.
TL;DR / Key Takeaways
- Primary function: Estimate Gemini API expenses associated with context caching.
- Key variables: Cached token count, request volume, cache duration, and applicable token prices.
- Cost components: Cached input usage, cache storage, uncached input, and output generation.
- Best suited for: Developers, AI application builders, and teams evaluating recurring Gemini API workloads.
How to Use Gemini API Caching Cost Estimator?
Use the estimator with representative workload measurements and the pricing applicable to your selected Gemini model. The exact fields and controls depend on the calculator implementation, but a reliable estimate should account for the following variables.
- Cached context tokens: The number of tokens in the reusable context. Examples include a product knowledge base, a code repository, or a lengthy instruction set.
- Requests per period: The number of API requests that reuse the cached context during the calculation period.
- Cache duration: How long the context remains stored. Explicit caching uses a time-to-live (TTL), and storage costs depend on the cached token volume and duration.
- Model pricing: The applicable standard input, cached input, and storage prices. Pricing may differ by model and service tier.
- Additional input and output: Tokens that are not served from the cache and tokens generated by the model must be accounted for separately.
Enter measured token counts where possible rather than estimating token usage from character count alone. If the estimator provides separate fields for daily and monthly usage, keep the request volume, storage duration, and billing period consistent.
Input and Output Example
Consider a hypothetical workload that reuses a 100,000-token context for 1,000 requests. Assume the context is stored for one hour and the applicable illustrative prices are $1.00 per million tokens for ordinary input, $0.25 per million cached input tokens, and $1.00 per million tokens per hour for cache storage.
Illustrative inputs
- Reusable context: 100,000 tokens
- Requests: 1,000
- Cache duration: 1 hour
- Standard input price: $1.00 per million tokens
- Cached input price: $0.25 per million tokens
- Storage price: $1.00 per million tokens per hour
Uncached input cost
100,000 × 1,000 ÷ 1,000,000 × $1.00 = $100.00
Cached input cost
100,000 × 1,000 ÷ 1,000,000 × $0.25 = $25.00
Cache storage cost
100,000 ÷ 1,000,000 × 1 hour × $1.00 = $0.10
Estimated savings on the reusable context
$100.00 − $25.00 − $0.10 = $74.90
This example isolates the reusable context. It excludes cache creation charges, additional uncached input, output tokens, and other API charges. The prices are illustrative rather than a statement of current pricing for any specific Gemini model.
Gemini API Caching Cost Reference Table
These formulas provide a practical reference for interpreting a caching estimate. All token prices should be expressed in the same currency and per-million-token unit before calculating costs.
| Cost component | Calculation | Purpose |
|---|---|---|
| Uncached input | Tokens × requests × standard price ÷ 1,000,000 | Baseline cost for repeatedly sending the reusable context |
| Cached input | Cached tokens × cache reads × cached-input price ÷ 1,000,000 | Cost of processing cached context on requests |
| Cache storage | Stored tokens × hours × storage price ÷ 1,000,000 | Cost of retaining cached context |
| Additional input | Uncached input tokens × standard input price ÷ 1,000,000 | Cost of new instructions or data outside the reusable context |
| Output generation | Output tokens × output price ÷ 1,000,000 | Cost of generated responses, including applicable billable output tokens |
| Net savings | Baseline total − cached total | Difference between comparable uncached and cached workloads |
Important: These formulas assume the cached context is reused for the stated number of requests and that the specified storage duration is billed as entered. Actual billing depends on the selected model, caching method, service tier, and applicable pricing rules.
How Gemini API Context Caching Works
Context caching allows a substantial context to be reused across multiple requests instead of repeatedly transmitting and processing the same content as ordinary input. Gemini supports implicit caching for eligible models and explicit caching, in which an application creates a cache and specifies its lifetime.
- Implicit caching: Eligible models may automatically recognize repeated prompt prefixes and apply caching discounts when cache hits occur. Actual savings depend on workload patterns and cache hits.
- Explicit caching: An application creates a reusable cache object and references it in subsequent requests. Storage costs depend on cached token count and duration.
- Cached input billing: Cached tokens are billed at the applicable cached-input rate rather than the standard input rate.
- Remaining usage: Additional input and generated output continue to incur applicable charges.
For official technical details, consult the Gemini API context caching documentation and the official Gemini API pricing page.
How to Interpret the Cost Estimate
Compare the total cost of equivalent workloads, not just the cached-input rate. A cached workload can have a lower input-token rate and still cost more if the context is stored for a long time but rarely reused.
The core calculation is:
Net savings = Uncached workload cost − Cached workload cost
Savings percentage can be calculated as:
(Net savings ÷ Uncached workload cost) × 100
For a simplified workload with a single reusable context, the break-even request count can be estimated as:
Break-even requests = Cache storage and creation costs ÷ Savings per request before storage
This simplified formula applies only when the savings per request are positive and usage remains reasonably consistent. A more complete estimate should include changing cache lifetimes, cache misses, cache recreation, additional inputs, and output costs.
Edge Cases and Limitations
- Low request volume: Storage costs can outweigh the discount when a cached context is rarely reused.
- Long cache duration: Keeping a large context stored for longer than necessary can increase total cost.
- Cache misses: Implicit caching does not guarantee that every request receives a cache discount.
- Changing context: Workloads that frequently modify their underlying documents or instructions may need new caches or different cache-management strategies.
- Mixed token types: Text, image, audio, and video tokens may have different applicable rates. Use the correct pricing category for the workload.
- Model and tier differences: Prices vary by model and service tier and can change over time.
- Invalid or incomplete inputs: Missing prices, inconsistent time units, or an incorrectly entered token count can produce misleading estimates.
This estimator is intended for budgeting and scenario analysis. Its results should be checked against current official pricing and actual usage metadata before making production cost commitments.
Frequently Asked Questions
Does Gemini API context caching always save money?
No. Savings depend on how often the cached context is reused, the difference between standard and cached input prices, and the cost of storing the context. Low reuse or excessive storage duration can reduce or eliminate the benefit.
What is the difference between cached input cost and cache storage cost?
Cached input cost covers processing cached tokens when a request uses the cache. Cache storage cost covers retaining the cached content for its billed lifetime. They are separate cost components.
How do I calculate Gemini API caching savings?
Calculate the comparable uncached workload cost, subtract the cached-input cost and applicable storage and creation costs, and then compare the totals. Include other input and output charges when evaluating the complete workload.
Does implicit caching guarantee a cache hit?
No. Implicit caching can provide discounts for eligible requests when caching conditions are met, but a cache hit is not guaranteed for every request. Actual cache usage should be evaluated using the available usage metadata.
Which pricing information should I use?
Use the current official pricing for the exact Gemini model, service tier, input modality, cached-input usage, and storage rate. Do not assume that all Gemini models share the same prices.
Are output tokens included in caching savings?
Not automatically. Output tokens are billed separately under the applicable output pricing. A complete comparison should include output generation in both scenarios, even when the output volume is expected to remain unchanged.
Author: Jordan Miller, AI Infrastructure Writer specializing in API usage and cost estimation.
Technical Review: This content explains the cost-model assumptions for reusable Gemini API context, cached-input usage, and storage duration. Validate the estimator's implementation and current model pricing before relying on its numerical results.