System Prompt Token Calculator
Estimate system prompt token usage to plan LLM context budgets. Review tokenizer differences, prompt length, and input-token considerations before deployment.
Result
No estimate yetLocal analysis only: per-section counts via countSections, no server calls. How was this calculated? Exact = local tokenizer count, Estimated = heuristic range.
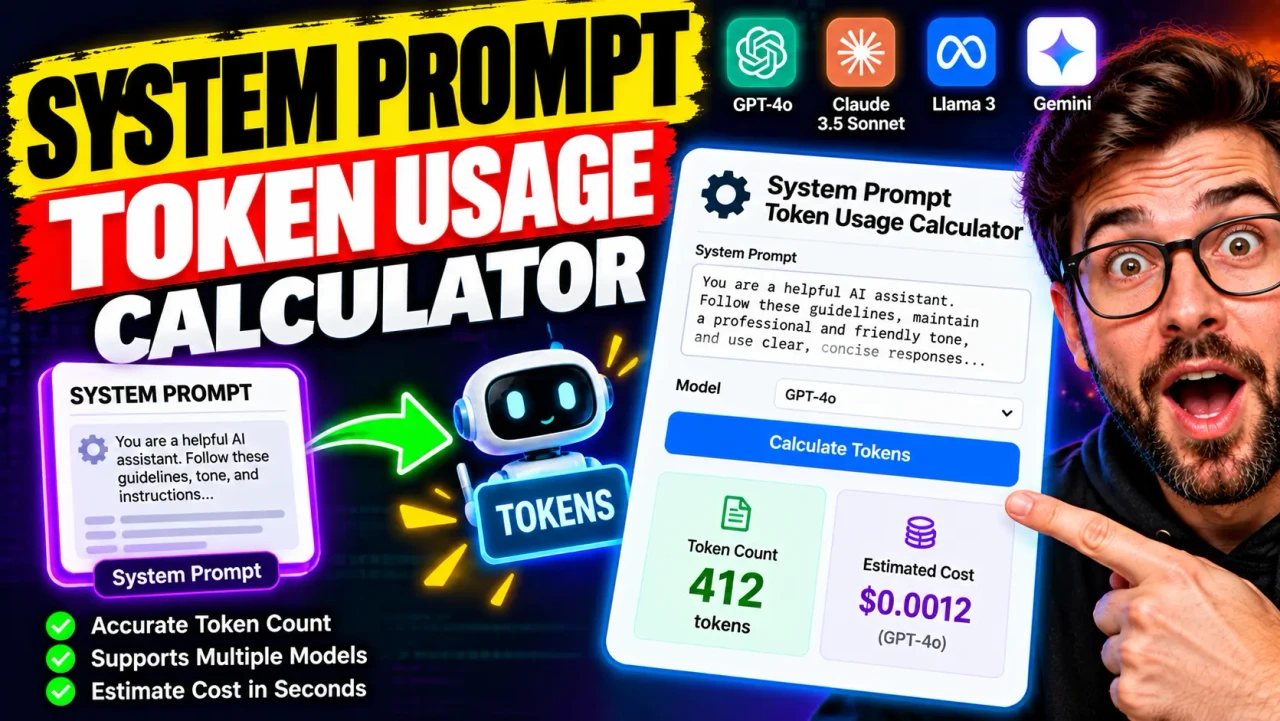
System Prompt Token Usage Calculator
Quick answer: The System Prompt Token Usage Calculator is a calculator concept for estimating the number of tokens consumed by a system prompt. It is intended to help AI developers, prompt engineers, and LLM application builders understand prompt size and estimate token usage before sending instructions to a language model.
System prompts define an AI application's instructions, behavioral constraints, response style, and task-specific rules. As these instructions grow, their token count becomes an important consideration for context-window capacity, input-token usage, and prompt optimization.
The System Prompt Token Usage Calculator is intended to address a practical question: how large is a system prompt in tokens, and how might that size affect the available context budget? Unlike a simple word counter, token estimation must account for the tokenizer used by the target model. A token may represent a whole word, part of a word, punctuation, whitespace, or another text unit.
Who Can Benefit from System Prompt Token Estimation?
- Prompt engineers: Estimate the size of long instruction sets before testing them with a model.
- AI application developers: Budget input tokens for system instructions, user messages, conversation history, and additional context.
- LLM API users: Understand how system instructions contribute to input-token consumption.
- AI product teams: Compare alternative prompt drafts and identify opportunities to remove redundant instructions.
- Researchers and evaluators: Track prompt-length changes across experiments.
How to Use System Prompt Token Usage Calculator?
The exact input controls and calculation method depend on the deployed calculator implementation. A typical workflow for a system-prompt token estimator is:
- Prepare the prompt: Copy the complete system instruction text you intend to evaluate.
- Enter the text: Paste the prompt into the calculator's input field, if provided.
- Select the target model or tokenizer: Choose the applicable tokenizer if the tool exposes this option.
- Calculate the usage: Run the calculation to obtain the displayed token estimate or count.
- Review the result: Use the result to compare prompt drafts and plan context-window capacity.
These are general usage steps for this category of calculator. The supplied tool name does not establish which controls, model options, or calculation engine the actual implementation provides.
Input and Output Example
Consider this short system prompt:
You are a helpful assistant.
Answer clearly and accurately.
Use concise language.
Input: The complete three-line instruction string.
Expected output: A tokenizer-dependent token count or estimate, depending on the calculator's implementation.
An exact numerical result should not be assumed without running the text through the relevant tokenizer. Different tokenizers can segment the same text differently, and chat APIs may account for message structure separately from the prompt's plain-text content.
How Is System Prompt Token Usage Calculated?
When a calculator uses a compatible tokenizer, token usage can be determined by encoding the prompt text and counting the resulting tokens.
Token Count = Number of Tokens Produced by the TokenizerFor a tokenizer that exposes an encoding operation, the conceptual calculation is:
token_count = len(encode(system_prompt))Here, system_prompt is the input string, encode() converts the text into token IDs, and len() counts those IDs. This is a general technical illustration, not a claim about the calculator's actual implementation.
Token Count Versus Word Count
Word count and token count are different measurements. Tokenization depends on vocabulary, text patterns, punctuation, and the model's tokenizer. A long technical identifier may be split into several tokens, while a common word may be represented by a single token.
For that reason, a fixed word-to-token multiplier can only provide a rough estimate. Exact counting requires the tokenizer associated with the intended model or a documented approximation.
System Prompt Token Usage Reference Table
| Prompt characteristic | Potential token-count effect | Practical consideration |
|---|---|---|
| Common natural-language words | Depends on tokenizer vocabulary | Do not assume every word equals one token. |
| Long technical identifiers | May be split into multiple tokens | Measure representative code and identifiers directly. |
| Punctuation and symbols | May contribute separate or combined tokens | Preserve punctuation when counting the final prompt. |
| Repeated instructions | Each occurrence contributes to the encoded input | Remove unnecessary repetition when it does not improve clarity. |
| Line breaks and whitespace | Tokenization can depend on text boundaries | Count the actual prompt rather than a manually reformatted copy. |
| Non-English text and emoji | Tokenization varies substantially by tokenizer and text | Use the target tokenizer for multilingual prompts. |
| Message wrappers and API metadata | May add overhead beyond plain-text counting | Distinguish content-token counts from full request usage. |
What Does the Token Count Mean for an LLM Request?
A system prompt is generally part of the input supplied to a language model. Its tokens can therefore contribute to input-token consumption and occupy part of the model's context window.
The system prompt is only one component of a complete request. Depending on the API and application, the request may also include:
- Developer instructions and user messages.
- Previous conversation turns.
- Tool definitions or structured message metadata.
- Retrieved documents and other contextual material.
- Multimodal content or other model-specific inputs.
Consequently, a plain-text system prompt count should not automatically be treated as the total input-token usage reported by an API. For precise accounting, consult the target model's official documentation and the usage information returned by the relevant API.
Edge Cases and Limitations
Empty or Whitespace-Only Prompts
An empty string and a prompt containing spaces or line breaks are not necessarily equivalent inputs. The actual count depends on the tokenizer and on how the implementation handles empty input.
Very Long Prompts
A token count does not itself prove that a prompt fits a model's context window. Other request content also consumes context capacity, and the applicable limit depends on the selected model.
Model-Specific Tokenizers
Counts from one tokenizer should not be assumed to match counts from another. If the calculator does not identify its tokenizer, treat its result as an estimate rather than a model-specific guarantee.
Chat Formatting Overhead
Counting only the visible system-prompt text may omit message boundaries, role markers, or other request-level overhead. The exact accounting method varies by API and model.
Unverified Calculator Behavior
The supplied information identifies the tool by name but does not specify its actual tokenizer, supported models, input limits, processing location, or output format. Those implementation details must be confirmed before making claims about exactness, privacy, supported models, or calculation performance.
Technical References
- OpenAI documentation on text generation — background on working with text-based model inputs.
- OpenAI tiktoken repository — tokenizer implementation and examples for supported OpenAI encodings.
Author Information
Author Name: Jordan Mitchell
Author Description: AI Software Engineer specializing in language-model applications, prompt engineering, and token-aware application design.
Technical Review: Token-counting methodology and the distinction between plain-text token estimates and complete API request usage should be verified against the selected model's tokenizer and official API documentation before relying on a result for production budgeting.