Gemini Batch Api Discount Calculator For Api Cost Savings
Estimate Gemini Batch API costs and potential savings by comparing standard and batch token rates. Review input, output, and workload assumptions before budgeting.
Please complete this field to continue.
Please complete this field to continue.
Please complete this field to continue.
Please complete this field to continue.
Results
Gemini Batch Api Discount Calculator
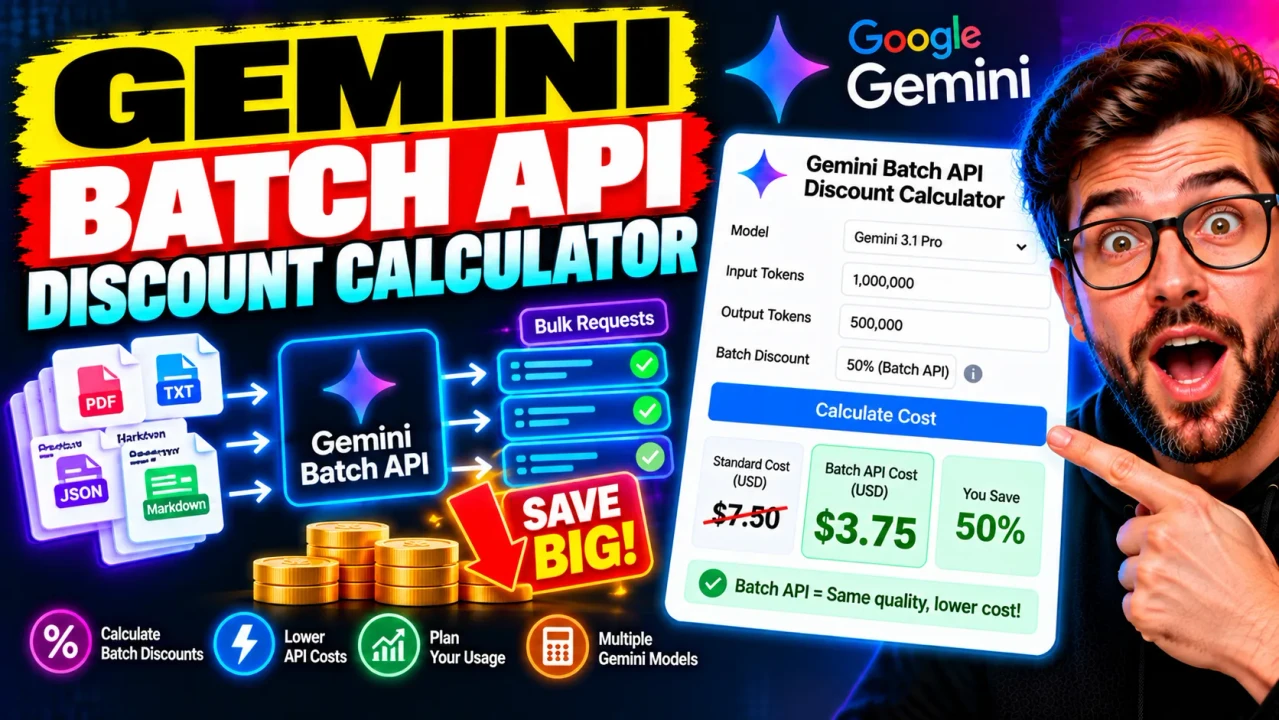
Quick answer: The Gemini Batch API Discount Calculator is intended to help users estimate potential cost savings when processing eligible requests through Google's Gemini Batch API instead of standard synchronous API requests. It is designed for developers, AI engineers, and teams estimating batch-processing costs. Exact calculations require the applicable model, standard pricing, batch pricing, and request usage.
The Gemini Batch API Discount Calculator focuses on one practical budgeting question: how much could a Gemini workload cost when submitted through batch processing rather than standard API processing? It can help developers compare pricing scenarios, estimate potential savings, and evaluate whether non-immediate AI workloads are suitable for batch execution.
Typical use cases include processing large collections of text, generating embeddings where supported, evaluating model outputs, classifying datasets, and running other workloads that do not require an immediate response. Actual eligibility depends on the model, endpoint, and current Google API documentation.
Key Takeaways
- Primary function: Compare estimated standard API costs with batch API costs.
- Important inputs: Model-specific pricing and workload usage, including input and output tokens where applicable.
- Expected output: Estimated costs, potential savings, and discount percentage when the required pricing data is available.
- Best suited for: Developers and teams planning non-real-time Gemini workloads.
How to Use Gemini Batch Api Discount Calculator?
Use the calculator by supplying the pricing and workload values requested by its actual interface. The specific input fields and supported units must be confirmed against the deployed implementation; the following describes the data needed for a reliable comparison rather than claiming a particular interface layout.
- Select the Gemini model: Use the model that will handle the workload. Pricing can vary between models and model versions.
- Enter standard pricing: Supply the applicable regular API rate for each relevant billing category.
- Enter batch pricing: Supply the corresponding batch rate, or the verified batch discount if that is what the calculator accepts.
- Estimate workload usage: Provide expected input tokens, output tokens, request counts, or other applicable usage measures.
- Review the comparison: Compare the estimated regular cost, batch cost, absolute savings, and percentage savings when those outputs are supported.
Understanding the Batch API Discount
Batch processing is useful when requests can be submitted for asynchronous processing instead of requiring an immediate response. A lower unit price can reduce costs for eligible workloads, but the total savings depend on the model, token mix, request volume, and the current pricing schedule.
The discount percentage should be calculated from comparable prices for the same model and billing category. Do not compare a standard input-token rate with a batch output-token rate, or mix prices from different model versions.
Formula Used for Cost and Savings Estimates
For a simple token-priced workload, calculate the standard and batch costs separately:
Standard Cost = (Input Tokens / 1,000,000 × Standard Input Rate) + (Output Tokens / 1,000,000 × Standard Output Rate)
Batch Cost = (Input Tokens / 1,000,000 × Batch Input Rate) + (Output Tokens / 1,000,000 × Batch Output Rate)
Estimated Savings = Standard Cost − Batch Cost
Discount Percentage = (Estimated Savings / Standard Cost) × 100
- Input Tokens: Expected tokens sent to the model.
- Output Tokens: Expected tokens generated by the model.
- Standard Input Rate: Regular API price per million input tokens.
- Standard Output Rate: Regular API price per million output tokens.
- Batch Input Rate: Batch API price per million input tokens.
- Batch Output Rate: Batch API price per million output tokens.
These formulas assume that the relevant prices use the same currency and billing units and that all listed usage is billed at the supplied rates. If the model uses additional billing categories, such as separately priced cached input or other specialized token classes, include those categories separately rather than combining them with ordinary input tokens.
Worked Example: Estimating Potential Savings
The following is an illustrative calculation, not a statement of current Gemini API pricing. Replace the example rates with verified prices for the selected model before using the results for budgeting.
| Input | Example value |
|---|---|
| Input tokens | 10,000,000 |
| Output tokens | 2,000,000 |
| Standard input rate | $1.00 per million tokens |
| Standard output rate | $4.00 per million tokens |
| Batch input rate | $0.50 per million tokens |
| Batch output rate | $2.00 per million tokens |
Standard cost: (10 × $1.00) + (2 × $4.00) = $18.00.
Batch cost: (10 × $0.50) + (2 × $2.00) = $9.00.
Estimated savings: $18.00 − $9.00 = $9.00.
Illustrative discount: ($9.00 / $18.00) × 100 = 50%.
This example demonstrates why a single headline discount may not fully describe a workload. When input and output tokens have different rates, the effective overall discount depends on the ratio of input to output usage.
Gemini Batch API Pricing Reference
Use the following reference to organize the values required for a meaningful comparison. It describes pricing categories to check; it is not a live price list, and the applicable categories depend on the selected model and API.
| Pricing category | Value to obtain | Calculation use |
|---|---|---|
| Standard input tokens | Regular input rate per billing unit | Calculates standard input cost |
| Batch input tokens | Batch input rate for the same model | Calculates batch input cost |
| Standard output tokens | Regular output rate per billing unit | Calculates standard output cost |
| Batch output tokens | Batch output rate for the same model | Calculates batch output cost |
| Cached or specialized tokens | Separate rate, if applicable | Prevents billing categories from being mixed |
| Request volume | Expected request count and token totals | Estimates the workload's total cost |
For authoritative pricing and feature eligibility, consult the official Gemini API pricing documentation and the official Gemini Batch API documentation. Verify prices and applicable terms before using any estimate for procurement or production budgeting.
How the Calculation Works
- Normalize usage: Convert token counts to the same billing unit used by the pricing schedule, commonly tokens per million for the illustrative formulas above.
- Calculate each category: Multiply the usage for each category by its matching rate.
- Sum the costs: Add the applicable categories to obtain the standard and batch estimates.
- Compare totals: Subtract the batch estimate from the standard estimate to obtain estimated savings.
- Calculate the effective discount: Divide savings by standard cost and multiply by 100, provided standard cost is greater than zero.
Edge Cases and Limitations
- Zero standard cost: If the standard cost is zero, the percentage discount is undefined. Report the absolute savings instead.
- Equal pricing: Equal standard and batch costs produce zero savings and a 0% discount when standard cost is positive.
- Batch pricing is higher: A negative savings result indicates a higher estimated batch cost under the entered rates. Check that the prices and billing units are correct.
- Different model versions: Compare prices for the same model and applicable version. Otherwise, the result may reflect a model change rather than a batch discount.
- Input and output mix: Workloads with different token ratios can have different effective discounts even when individual pricing categories have fixed rates.
- Additional billing categories: Cached input, multimodal processing, or other specialized usage may need separate rates. Do not assume ordinary text-token prices cover every workload.
- Estimated usage: Actual consumption can differ from projected tokens. Treat the output as a budget estimate, not an invoice guarantee.
- Eligibility and turnaround: Not every workload or model necessarily supports the same batch features. Confirm current API requirements and asynchronous processing expectations.
Technical Disclaimer: Cost estimates depend on the rates and usage assumptions entered. Verify current official pricing, model eligibility, token accounting, and applicable billing terms before committing to a workload budget.
Frequently Asked Questions
How is the Gemini Batch API discount percentage calculated?
Subtract the estimated batch cost from the standard cost, divide the savings by the standard cost, and multiply by 100. The calculation requires a positive standard cost.
Can input and output tokens have different discounts?
Yes. If the applicable pricing schedule has different input and output rates, calculate each category independently. The effective discount for the whole workload depends on the usage mix.
Which prices should I enter?
Use the current standard and batch prices for the same Gemini model and matching billing categories. Check Google's official pricing documentation rather than relying on example rates.
Does this calculator show the exact amount Google will bill?
No estimate should be treated as a guaranteed invoice total. Actual charges depend on measured usage, applicable pricing terms, supported billing categories, and any other charges that apply to the workload.
What happens when the standard cost is zero?
The percentage discount cannot be calculated because the formula divides by the standard cost. Report the absolute cost difference instead.
When should I use the Gemini Batch API?
Batch processing is worth evaluating when requests can be processed asynchronously and do not require immediate responses. Confirm model and workload eligibility and consider the required turnaround time before choosing batch processing.
Author Information
Author Name: Morgan Bennett
Author Description: Technical content specialist focused on API cost estimation, cloud computing, and AI application budgeting.
Technical Review: The pricing formulas, billing-category comparisons, and discount calculations should be checked against the selected Gemini model's current official pricing before publication or use.